
Technologies referenced in this playbook: Redis · API Gateways · Asked at: Stripe · Cloudflare · Google · Uber · Amazon · OpenAI · GitHub · Figma
Every time a developer calls Stripe’s /v1/charges endpoint, an application sends a prompt to OpenAI’s API, or Cloudflare blocks a wave of login bots at the network edge, a distributed rate limiter sits at the front door answering one question:
On a single server, this is a 20-line coding problem. Keep an in-memory hash map of user_id -> request_count. Add 1 on every request. Return HTTP 429 Too Many Requests when the count crosses the limit. Done.
At the scale of 1,000,000 requests per second across 50 stateless API Gateway servers (meaning any gateway can handle any request, and gateways do not store permanent user session state locally) and 100 million active users, that simple approach breaks down:
- If each stateless gateway counts only in its own memory, a user whose requests are spread across 50 gateways gets 50x their actual limit.
- If every gateway makes a naive network call to a central database on every request, you add latency to every API call in the company.
- Worst of all, if that central rate-limiting database slows down or crashes, a poorly designed rate limiter will either block 100% of real customers or let a traffic spike overwhelm your backend databases.
1Understanding the Problem (The Staff Reframe)
When you are asked to design a rate limiter, the first thing to recognize is that "rate limiting" is actually three different problems sharing one name. Before choosing an algorithm or database, you have to ask: What failure are we protecting against?
Each type of rate limiter has a different business goal, needs a different level of accuracy, and behaves differently when the rate limiter itself fails:
| Type of Rate Limiter | Real-World Examples | Primary Goal | Accuracy Needed | If the Rate Limiter Breaks... | Who Pays the Cost of Mistakes? |
|---|---|---|---|---|---|
| 1. API Abuse & Bot Protection | Cloudflare, AWS API Gateway, GitHub API | Protect backend servers from bots, scrapers, and accidental retry loops | Approximate (being off by ±5–10% is fine) | Fail-Open (Let traffic through; never take down the website because Redis hiccuped) | Infrastructure Team (absorbs a small extra traffic burst) |
| 2. Paid Quota & Billing Limits | OpenAI Tokens/Min, Twilio SMS Credits | Enforce paid plan limits so customers don't use unpaid compute | Strict / Exact (every token costs real money) | Fail-Closed (Reject or pause requests if we can't verify the customer's balance) | Finance / Business (letting extra requests through gives away paid usage for free) |
| 3. Multi-Tenant Fairness ("Noisy Neighbor") | Stripe Webhooks, Shared SaaS Clusters | Stop one heavy customer from hogging shared servers and slowing down others | Flexible (guaranteed minimum + shared extra capacity) | Drop Background Work First (Pause low-priority syncs so live checkouts keep working) | Product / Support (explaining to a big customer why their background jobs slowed down) |
2Requirements & Scope
For this design, we will build a server-side, request-level rate limiter for a high-traffic API platform (like Stripe, GitHub, or OpenAI). That means we are limiting individual HTTP requests (such as POST /v1/charges or GET /v1/items) on our servers rather than relying on client-side throttling, since clients can be modified or bypassed and cannot be trusted to regulate themselves.
Functional Requirements (Core Features)
- Identify Callers: The system should identify who is making each request (by user ID, API key, or IP address) so it can apply the appropriate rate limit to each caller.
- Enforce Configurable Rules: The system should limit HTTP requests based on flexible, configurable rules:
- By customer plan: e.g., Free tier (60 requests/min) vs. Enterprise tier (10,000 requests/min).
- By API endpoint: e.g.,
POST /checkout(10 requests/min) vs.GET /items(1,000 requests/min). - Across multiple time windows: e.g., enforcing both a short-term burst limit (500 requests/sec) and a daily quota (1,000,000 requests/day).
- Reject with
HTTP 429& Helpful Headers: When a caller exceeds their limit, the system should reject the request withHTTP 429 Too Many Requestsand return helpful headers (RateLimit-Limit,RateLimit-Remaining,RateLimit-Reset, andRetry-After) so well-behaved clients know when to retry. - Live Rule Updates (Control Plane): Engineers should be able to add or update rate-limit rules dynamically (including testing new rules in "dry-run / shadow mode" first) without redeploying or restarting servers.
Out of Scope
- Client-Side Throttling: While client SDKs should respect
Retry-Afterheaders, client-side rate limiting is out of scope because we are designing the server-side enforcement system. - Network-Level DDoS Attacks (Raw Packet Floods): Volumetric L3/L4 network attacks (like SYN floods or UDP amplification) are handled upstream by our CDN or cloud provider (Cloudflare, AWS Shield) before traffic reaches our API servers.
- Monthly Customer Invoicing & Billing Statements: Calculated asynchronously in the background via event streams (Kafka → Billing Database), not on the live request path.
3Non-Functional Requirements & Scale Math
Non-Functional Requirements
- Latency: Under 1ms average and < 2ms p99 added to the request (< 0.05ms when served from local gateway memory).
- Availability: 99.999% uptime. If the rate-limiting database slows down or crashes, it must never take down customer APIs (Fail-Open to a safe local memory limit, plus an immediate alert to on-call).
- Accuracy: Being off by ±5–10% across gateways during a sudden burst is acceptable for abuse protection, as long as normal API traffic is counted accurately.
- Fast Local Regions: A user in Europe must be checked against a European server, never waiting 75ms for a round-trip across the Atlantic to a US database on every request.
Back-of-the-Envelope Scale Math
Four quick calculations tell us what our architecture must handle:
- Peak Traffic: 1,000,000 requests/sec (500,000 req/sec average) across 50 stateless API Gateway servers per region (~20,000 req/sec per server).
- Active Users / Callers: 100,000,000 unique keys per hour (
user_id,api_key, and IP addresses). - Total Redis Memory: Each user counter takes ~100 bytes (key name + 8-byte token count + 8-byte timestamp + Redis hash overhead). Across 100,000,000 active keys, 100,000,000 × 100 bytes ≈ 10 GB of RAM.
- Cross-Continent Latency: US-East (Virginia) ↔ Europe (Frankfurt) ≈ 75ms network round-trip.
4Core Data & API Contract
Core Concepts
- Caller ID: Who is making the request (
user_98a7f,key_live_123, or203.0.113.0). - Rate Limit Rule: The policy for an endpoint and plan, defining
bucket_capacity(max burst allowed at once) andrefill_rate(how many tokens are added per second). - Token Bucket State: The live counter in Redis for a user, storing just two numbers:
tokens_remainingandlast_refilled_at_ms. - Local Token Lease: A small batch of tokens (e.g., 50 tokens) temporarily checked out into a gateway server's RAM for a high-traffic user so the gateway doesn't have to call Redis on every request.
Where Should the Rate Limiter Live? (And How It Identifies Callers)
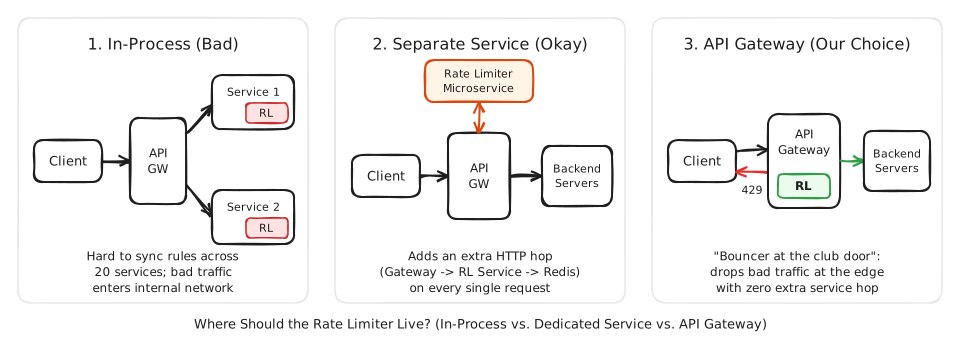
When an interviewer asks "Where in your architecture does the rate limiter sit?", walk through the three options from worst to best:
- Bad: Library Inside Each Backend Service: If you import a rate-limiting library into every backend service, library versions quickly get out of sync, changing a rate limit would require redeploying 20 services instead of updating one gateway rule, and abusive traffic still travels all the way inside your internal network before getting dropped.
- Okay: Separate Rate-Limiting Microservice: Making an extra HTTP call from the API Gateway to a separate "Rate Limiter Service" on every request adds unnecessary network latency (now you pay for two network hops: Gateway → Rate Limiter Service → Redis) and adds one more service that can go down.
- Great: API Gateway Middleware ("Bouncer at the Club Door"): Rate limiting runs as an in-memory middleware step right inside the API Gateway. Bad traffic is dropped at the front door before touching your internal network or backend services, with zero extra microservice hops.
Because the API Gateway only sees the incoming HTTP request, interviewers often ask two practical follow-ups:
- How does the Gateway know a user's plan (
freevsenterprise) without querying a User Database? When a user logs in, our Auth Service includes theiruser_idandtierdirectly inside their signed JWT token (e.g.,{"sub": "usr_98a7f", "tier": "enterprise"}). For API keys, the gateway caches theapi_key -> tiermapping in local RAM. That way, the gateway knows who the caller is and what plan they are on in < 0.01ms with zero database lookups. - What if multiple rules apply to the same request? A single request might match a per-user rule (100 req/s), a per-endpoint rule (10 req/s on
POST /v1/charges), and a global rule. The gateway checks all matching rules in a single Redis call and enforces the most restrictive result: if any matching bucket is empty, the request is rejected withHTTP 429.
Inside the API Gateway, the rate-limit check looks like a simple function call:
// Input to the Gateway Rate Limiter module
interface RateLimitRequest {
  caller_id: string;    // e.g., "usr_98a7f"
  route: string;        // e.g., "POST:/v1/charges"
  tier: string;         // e.g., "enterprise" | "free"
  cost: number;         // Default: 1 (or N tokens for heavy batch/AI endpoints)
}

// Output returned in < 1ms
interface RateLimitDecision {
  allowed: boolean;        // true = forward to backend; false = return HTTP 429
  limit: number;           // RateLimit-Limit header
  remaining: number;       // RateLimit-Remaining header
  retry_after_sec: number; // Retry-After header (if blocked)
}
HTTP Response When a Request Is Blocked
When allowed == false, the API Gateway rejects the request immediately at the front door:
HTTP/1.1 429 Too Many Requests
Content-Type: application/json
RateLimit-Limit: 100
RateLimit-Remaining: 0
RateLimit-Reset: 1712354460
Retry-After: 12

{
  "error": {
    "code": "rate_limit_exceeded",
    "message": "You have exceeded the limit of 100 requests per minute. Please retry in 12 seconds."
  }
}
5Choosing the Right Algorithm (Token Bucket)
Before scaling across 50 servers, let's establish how a rate limiter counts requests for a single user. Even if you haven't touched rate-limiting algorithms in years, you only need to know the five standard algorithms, how each one works with a quick number example, and why Token Bucket is the industry choice for APIs.
1. Fixed Window Counter
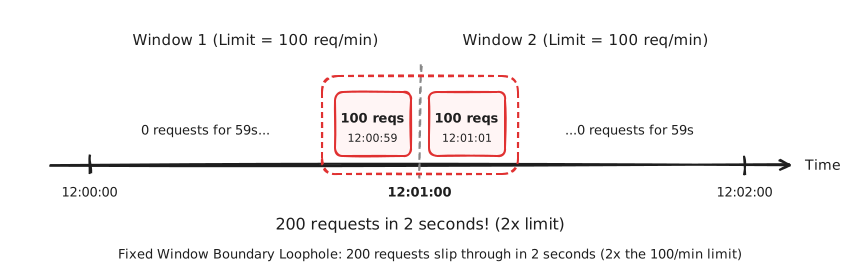
The simplest approach divides time into fixed clock windows (such as 1-minute buckets: 12:00:00–12:00:59, 12:01:00–12:01:59) and keeps a single integer counter per user for the current window.
- How it works: When a request arrives from Alice at 12:00:15, we increment the key
"alice:12:00". If the counter is at or below her 100 requests/min limit, we allow the request; once it hits 101, we reject new requests withHTTP 429until the clock ticks over to 12:01:00.
{
  "alice:12:00": 100,
  "alice:12:01": 5,
  "bob:12:00": 20
}
- Pros: Dead simple to build (
INCR+EXPIRE 60sin Redis) and uses almost zero memory (one integer per user). - Why it loses (The Minute-Boundary Loophole): If Alice sends 100 requests at 12:00:59 (the last second of Window 1) and another 100 requests at 12:01:01 (the first second of Window 2), both windows think she stayed within 100 requests/min, but she just hammered your servers with 200 requests in 2 seconds (2x your intended limit):
2. Sliding Window Log
To eliminate the boundary loophole completely, Sliding Window Log throws away fixed clock buckets and instead stores a sorted list of every individual request's exact timestamp for each user (for example, inside a Redis Sorted Set).
- How it works (with a 100 req/min limit): When Alice sends a request at 12:01:15, the limiter:
- Deletes all timestamps from Alice's list older than 60 seconds ago (anything before 12:00:15).
- Counts how many timestamps remain in the list.
- If the count is under 100, adds 12:01:15 to the list and allows the request; otherwise rejects it.
- Pros: 100% exact across any rolling 60-second window. It is impossible to sneak 2x traffic across a minute boundary.
- Why it loses (Memory Explosion): Instead of storing one integer per user, you are storing one timestamp per request. If an enterprise customer has a limit of 10,000 requests/min, you have to store 10,000 timestamps (~640 KB in a Redis Sorted Set) for that single user. Across millions of users, Redis runs out of RAM and spends too much CPU scanning and deleting old timestamps on every call.
3. Sliding Window Counter
Sliding Window Counter is a clever middle ground used by Cloudflare: it approximates a rolling window using only two integers (the previous minute's total count and the current minute's count so far).
- How the math works: Suppose the limit is 100 requests/min.
- In the previous minute (12:00–12:01), Alice made 80 requests.
- In the current minute (12:01–12:02), Alice has made 30 requests so far, and a new request arrives at 12:01:18 (which is 30% of the way into the current minute).
- Because our rolling 60-second window (12:00:18 to 12:01:18) covers the last 70% of the previous minute plus 100% of the current minute so far, we estimate Alice's rolling count as:
Formula:
Estimated Count = (70% × 80 previous) + 30 current = 56 + 30 = 86 requests - Since 86 < 100, the request is allowed!
- Pros: Fixes the boundary spike using only 2 numbers per user (~99.7% accurate in real Cloudflare production tests).
- Why we still prefer Token Bucket for APIs: Sliding Window Counter enforces a single flat average rate, so it doesn't let you configure a separate "short burst size" (e.g., allow 50 requests immediately when a page loads) vs. "steady refill speed" (e.g., 10 requests/sec thereafter).
4. Leaky Bucket (Queue-Based)
Imagine a bucket with a small hole in the bottom: water (requests) can pour in the top in sudden splashes, but water drips out the bottom to your backend workers at a strictly constant speed.
- How it works: Incoming requests are placed into a First-In, First-Out (FIFO) queue of fixed size. Backend workers pull requests from the queue at a steady rate (e.g., 10 requests/sec). If the queue fills up completely, new requests overflow and get rejected.
- Pros: Smooths out spiky traffic into a completely flat, steady stream for fragile downstream databases or background job processors.
- Why it loses for live user APIs: We want to reject bots fast (
HTTP 429), not put them in a waiting line! Queuing excess requests wastes server memory, adds unpredictable waiting delays to interactive API calls, and makes real users wait in line behind a burst of bot requests.
5. Token Bucket (Our Choice)
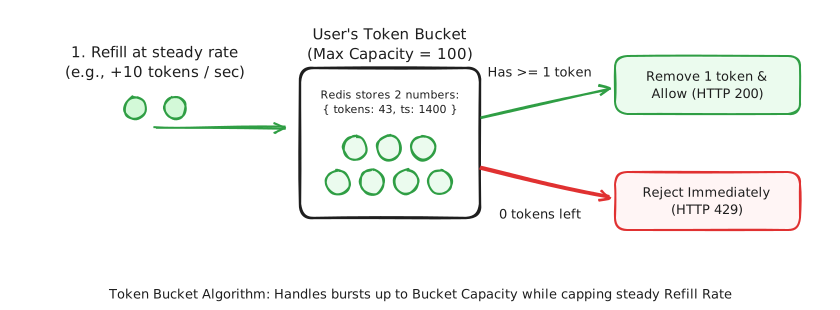
Real human API traffic is naturally bursty: when a user opens a dashboard, their browser fires 15 API requests at once to render the page, then sits quiet for 30 seconds. Token Bucket (used by Stripe, AWS, and OpenAI) handles this naturally.
-
Two Simple Knobs:
capacity(Max Burst): The maximum tokens a bucket can hold at once (e.g., 100 tokens). Even if a user is idle for 3 days, their bucket never holds more than 100 tokens.refill_rate(Steady Speed): How fast tokens are added back (e.g., 10 tokens per second = 0.01 tokens per millisecond).
-
How "Lazy Refill" Works (Why We Need Zero Background Timers): A common interview mistake is thinking you need a background timer running every second to add tokens to 100 million buckets in Redis. That would crash Redis. Instead, we only calculate refills lazily when a user actually makes a request: we check how much time passed since their last request (
now - last_updated), multiply by therefill_rate, and add those newly earned tokens on the spot:- Lazy Refill Formula:
new_tokens = min(capacity, current_tokens + (now - last_updated) × refill_rate)
- Lazy Refill Formula:
Step-by-Step Example: Token Bucket Math
Suppose user_42 has capacity = 100 tokens and refill_rate = 0.01 tokens/ms (10 tokens/sec):
- Saved in Redis at t = 1000ms:
rl:user_42has 40 tokens left (last_updated = 1000). - New request arrives 400ms later at t = 1400ms (cost = 1 token):
- Time passed: 1400 − 1000 = 400ms
- Newly earned: 400ms × 0.01 tokens/ms = 4 new tokens
- Refilled balance: min(100, 40 + 4) = 44 tokens
- Subtract 1 token: 44 − 1 = 43 tokens remaining
- Saved back to Redis at t = 1400ms:
rl:user_42now has 43 tokens remaining (last_updated = 1400) → ALLOWED
Summary Cheat Sheet: Comparing the 5 Algorithms
| Algorithm | How It Works | Memory per User | Pros | Cons & Why It Loses |
|---|---|---|---|---|
| 1. Fixed Window Counter | Simple counter per clock minute (alice:12:00). | Tiny (1 integer) | Easiest to build (INCR + EXPIRE). | Minute-Boundary Loophole: 100 requests at 12:00:59 + 100 at 12:01:01 lets 200 requests through in 2 seconds (2x spike). |
| 2. Sliding Window Log | Saves every request's exact timestamp in a sorted list (ZADD). | Huge (O(N) timestamps) | 100% exact rolling window. | Blows Up Memory: Saving 10,000 timestamps for one user takes ~640 KB. Across millions of users, Redis runs out of RAM. |
| 3. Sliding Window Counter | Blends previous minute's count + current minute's count (70% prev + 100% curr). | Tiny (2 integers) | Fixes the boundary loophole with tiny memory (~99.7% accurate). | Great for CDN traffic (Cloudflare), but doesn't let you set a separate "short burst size" vs. "steady refill rate". |
| 4. Leaky Bucket | Puts requests in a FIFO queue and processes them at a fixed speed. | Tiny | Smooths spiky traffic into a flat stream for backend workers. | Bad for Blocking Bots: Queuing bot requests wastes memory and makes real users wait in line behind bots instead of failing fast (429). |
| 5. Token Bucket (Our Choice) | Bucket holds up to capacity tokens and refills smoothly at refill_rate tokens/sec. | Tiny (2 numbers: tokens, timestamp) | Industry Standard (Stripe, AWS, OpenAI): Allows normal user bursts while capping steady speed. | Needs an atomic read-refill-subtract step in Redis so concurrent requests don't overwrite each other. |
6Building the Distributed Architecture Step-by-Step (Why 3 Simple Approaches Fail)
Now that we have our Token Bucket math, how do we run it across 50 stateless API Gateway servers at 1,000,000 requests/sec? Never jump straight to the final diagram. Walk the interviewer from the simplest idea through three attempts and show why each one breaks as traffic grows.
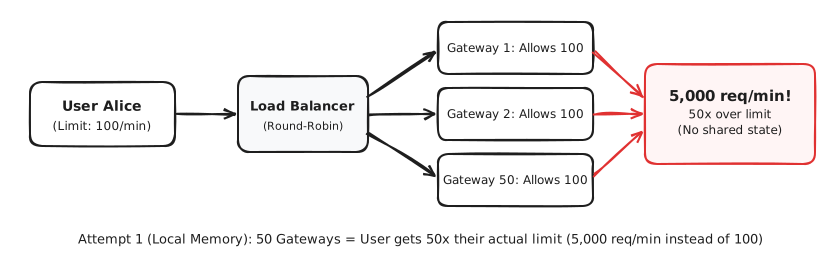
Attempt 1: In-Memory Counters on Each Gateway Server
Each of our 50 API Gateway servers keeps a local hash map of Token Buckets in its own RAM. When a request arrives, the gateway checks its own memory.
- Why it fails:
- 50 Gateways = 50x the Limit: Load balancers spread requests across all 50 gateways. If User A has a limit of 100 req/min and sends 5,000 requests, each of the 50 gateways only sees 100 requests and lets all 5,000 through!
- Why "Sticky Sessions" Don't Fix It: If you configure the load balancer so User A always goes to Gateway 1, a single heavy customer or botnet assigned to Gateway 1 will max out Gateway 1's CPU while the other 49 gateways sit idle.
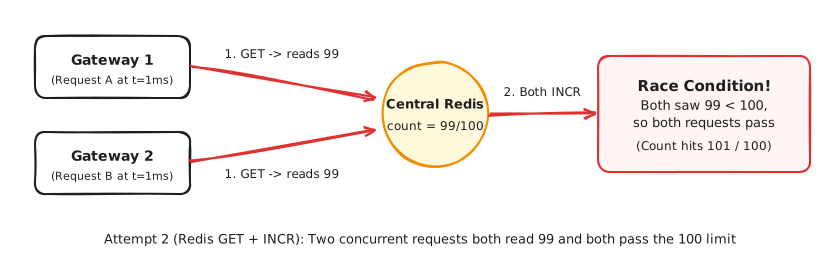
Attempt 2: Central Redis with GET + INCR on Every Request
To share counters across all 50 gateways, we move the counters into a shared Redis Cluster. On every request, the gateway reads the current count (GET) and updates it (SET / INCR).
- Why it fails:
- Race Conditions: Suppose User A has 1 token left (99 out of 100 used). Gateway 1 and Gateway 2 both run
GETat the exact same millisecond. Both see 1 token left. Both allow the request! During a fast burst of 50 parallel requests, dozens of extra requests slip through. - Extra Network Latency: Every API request has to wait for two separate network trips to Redis (read, then write).
- Race Conditions: Suppose User A has 1 token left (99 out of 100 used). Gateway 1 and Gateway 2 both run
Attempt 3: Central Redis with an Atomic Lua Script per Request
To fix the race condition, we combine the Token Bucket read, refill, and subtract into a single Redis Lua script (a small function stored inside Redis that Redis runs from start to finish in one step, like a database stored procedure, so no other request can sneak in the middle).
Why Use a Redis Lua Script Instead of Redis Transactions (WATCH / MULTI / EXEC)?
Interviewers often ask: "Why use a Lua script instead of standard Redis transactions (WATCH / MULTI / EXEC)?"
- The Problem with
WATCH / MULTI / EXEC: It uses optimistic locking. If 500 requests from a big customer hit the same counter at the same millisecond, only 1 succeeds and the other 499 abort because the counter changed while they were reading it. Those 499 gateway threads then have to retry over and over, creating a massive retry storm on Redis. - Why Lua Wins: Redis is single-threaded and runs a Lua script from start to finish without letting any other command sneak in the middle. All 500 requests execute one after another cleanly in < 0.1ms with zero failed transactions and zero retries.
Redis Lua Script for Token Bucket (Click to expand if you want to see the code)
-- KEYS[1]: Rate limit key (e.g., "rl:{usr_42}:post_charges")
-- ARGV[1]: Bucket capacity (e.g., 100)
-- ARGV[2]: Refill rate per millisecond (e.g., 0.01)
-- ARGV[3]: Tokens requested (1 for normal request, or batch size like 50 for a local lease)

local key = KEYS[1]
local capacity = tonumber(ARGV[1])
local refill_rate = tonumber(ARGV[2])
local requested = tonumber(ARGV[3])

-- Use Redis's own clock so clock differences between gateway servers don't break the math
local redis_time = redis.call("TIME")
local now = (tonumber(redis_time[1]) * 1000) + math.floor(tonumber(redis_time[2]) / 1000)

local state = redis.call("HMGET", key, "tk", "ts")
local tokens = tonumber(state[1])
local last_ts = tonumber(state[2])

if tokens == nil then
    tokens = capacity
    last_ts = now
else
    local elapsed = math.max(0, now - last_ts)
    tokens = math.min(capacity, tokens + (elapsed * refill_rate))
    last_ts = now
end

-- Automatically delete the key from Redis once enough idle time passes for the bucket to be 100% full again
local ttl_ms = math.ceil((capacity / refill_rate) * 2)

if tokens >= requested then
    tokens = tokens - requested
    redis.call("HMSET", key, "tk", tokens, "ts", last_ts)
    redis.call("PEXPIRE", key, ttl_ms)
    return { 1, math.floor(tokens), 0 } -- { allowed=1, remaining, retry_after_ms=0 }
else
    local deficit = requested - tokens
    local retry_after_ms = math.ceil(deficit / refill_rate)
    redis.call("HMSET", key, "tk", tokens, "ts", last_ts)
    redis.call("PEXPIRE", key, ttl_ms)
    return { 0, math.floor(tokens), retry_after_ms } -- { allowed=0, remaining, retry_after_ms }
end
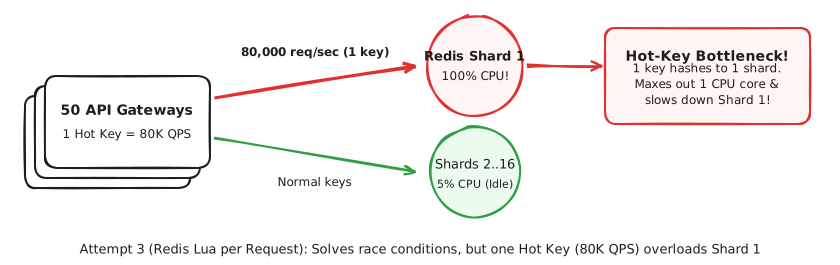
- Why Attempt 3 still hits a wall at 1,000,000 QPS:
- The "Hot Key" Single-Server Bottleneck: A Redis Cluster splits keys across 16 Redis servers by hashing the key name. That means every request for one big customer (
rl:tenant_shopify) always goes to the exact same Redis server (Shard 1). A single Redis server maxes out around 100,000 operations/sec. If one huge enterprise customer bursts to 80,000 req/sec during a flash sale, Shard 1's CPU hits 100%, slowing down every other customer whose key happens to live on Shard 1, even though the other 15 Redis servers are sitting idle! - Total Dependency on Redis: Every gateway still waits on Redis for 100% of requests. If a Redis shard freezes for 10 seconds during a failover, all 50 gateways stall waiting on it.
- The "Hot Key" Single-Server Bottleneck: A Redis Cluster splits keys across 16 Redis servers by hashing the key name. That means every request for one big customer (
Summary of the 3 Initial Attempts
| Approach | Pros | What Breaks at Scale | Interview Verdict |
|---|---|---|---|
| Attempt 1: Local Memory per Gateway | Super fast (< 0.01ms), no Redis needed. | 50 gateways = user gets 50x their limit. Sticky sessions overload individual servers. | Fails as soon as you have multiple gateway servers. |
Attempt 2: Central Redis (GET + INCR) | Shared counter across all 50 gateways. | Race conditions let parallel bursts slip through; 2 network trips per request. | Fails under concurrent traffic bursts. |
| Attempt 3: Central Redis + Atomic Lua | 100% accurate (zero race conditions, zero retries). | 1M network calls/sec on the live path; one hot customer (80K QPS) maxes out 1 Redis shard. | Great up to ~100K QPS; breaks on hot keys and Redis stalls. |
7The Production Architecture
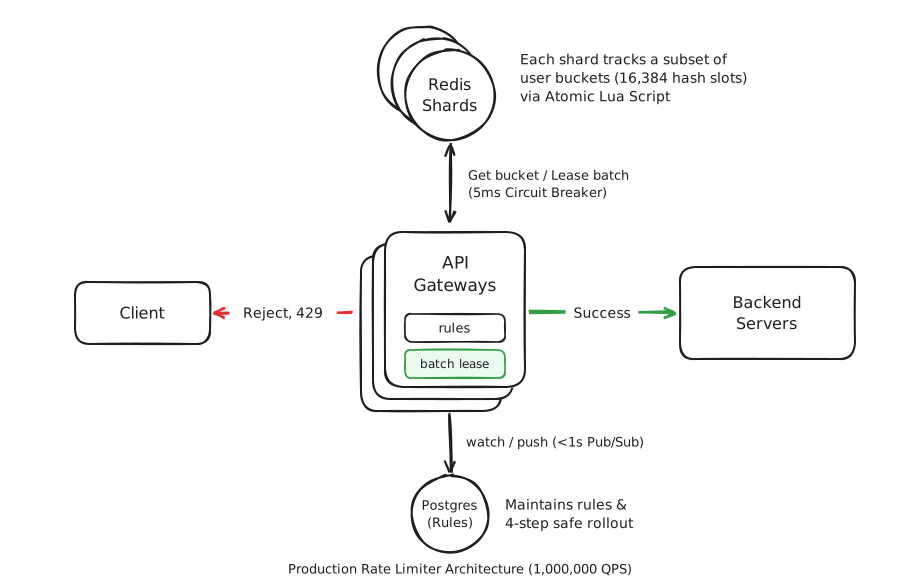
Our final design splits the system into three clean parts:
- The Live Request Path (Inside the API Gateway): Every incoming API request is checked right inside the gateway before reaching your backend:
- Normal Users: The gateway checks the user's counter in Redis. To keep this check under 1ms, each gateway maintains a pool of already-open network connections (a persistent TCP connection pool) to Redis so it reuses existing connections instead of wasting 20–50ms opening a new connection on every request.
- Heavy Users ("Hot Keys"): Instead of calling Redis on every single request, the gateway checks out a small batch of tokens into its own memory so repeat requests finish in < 0.05ms with zero network calls.
- Safety Cutoff (Circuit Breaker): If a Redis server slows down and takes longer than 5ms to reply, the gateway stops waiting for it and temporarily switches to counting in its own local memory so customer traffic never hangs.
- Rule Management (Control Plane): Lets engineers update rate-limit rules in PostgreSQL (or DynamoDB) and broadcasts changes to all 50 gateways in under 1 second via Redis Pub/Sub.
- Monitoring & Alerts: Tracks allowed, rejected (429), and bypassed requests, and pages the on-call engineer if Redis is being bypassed.
How "Batch Token Leasing" Works for Heavy Users
Why don't we check out batches of 50 tokens for every user?
- The Unused Token Problem: 95% of users make fewer than 5 requests per minute. If Gateway 1 checked out 50 tokens for a user with a 100 req/min limit who only made 1 request, the other 49 tokens would sit locked up in Gateway 1's memory where other gateways couldn't use them.
So the gateway uses a Two-Speed Approach:
- Normal Users (Low Traffic): The gateway calls Redis and asks for 1 token at a time.
- Heavy Users ("Hot Keys" Sending > 10 req/sec): When a gateway notices a specific API key or user getting hit heavily, it automatically switches to Batch Leasing for that key:
- Instead of asking Redis for 1 token on every call, the gateway asks Redis for a batch of 20 to 500 tokens at once (enough to cover roughly 250ms of that user's traffic) and keeps them in local RAM for up to 2 seconds.
- The next 19 to 499 requests are subtracted right in the gateway's memory in < 0.05ms with zero network calls to Redis, cutting Redis traffic for that hot key by 98–99%.
- Refilling in the Background Before Running Empty: When the gateway's local batch drops to 20% remaining (e.g., 40 tokens left out of 200), a background thread fetches the next batch from Redis before the local tokens run out, so live customer requests never wait on the network.
- Walkthrough of a 200-Token Batch Lease on Gateway 1:
- Request #1: Gateway 1 asks Redis for 200 tokens at once (1ms network call). Redis subtracts 200 tokens and Gateway 1 caches the remaining 199 tokens in local RAM.
- Requests #2–160: Served directly from Gateway 1 RAM in 0.05ms (0 Redis network calls).
- At Request #160 (20% left): A background thread quietly fetches the next 200 tokens from Redis while Requests #161–200 keep running from local RAM at 0.05ms without waiting.
How This Architecture Scales From 1,000 to 1,000,000+ QPS
In an interview, point out that you only add complexity when the traffic scale actually requires it:
| Traffic Scale | Recommended Architecture | Why |
|---|---|---|
| Under 10,000 req/sec | Built-in Gateway Limiter (Cloudflare, AWS API Gateway, Envoy) or 1 Redis Server | A single Redis node easily handles 100,000 ops/sec. Don't over-engineer small systems. |
| 10,000 – 100,000 req/sec | Sharded Redis Cluster (3–8 nodes) + Atomic Lua Script per request (Attempt 3) | Spreads keys across shards; no need for local token leasing unless you have a single massive hot key. |
| 100,000 – 1,000,000+ req/sec | Redis Cluster + Gateway Batch Token Leasing + 5ms Circuit Breaker (Section 7) | Prevents hot keys (80K QPS) from overloading a single Redis shard and cuts Redis network calls by 98%. |
| Global Multi-Continent | Independent Regional Redis Clusters + Regional Quota Splitting (Deep Dive 5) | Avoids the 75ms cross-Atlantic network penalty and keeps European user IPs inside Europe (GDPR). |
8Database & Key Design
A common interview follow-up is: "Wait, where do the rate limit rules live? Why Redis for counters, and why PostgreSQL or DynamoDB for rules?"
The right approach separates the Live Counter Store (where database choice is critical) from the Rule Store (where almost any database works):
| Storage Layer | Technology | What It Stores | Speed & Scale | Why It Fits This Job |
|---|---|---|---|---|
| 1. Gateway Local Memory | In-Process RAM on each of the 50 Gateways | Active rate-limit rules, 2s token batches for hot users, and 10s blocked-caller cache. | < 0.05ms | Absorbs 99% of hot-key and repeat-bot traffic with zero network calls. Resets if gateway restarts. |
| 2. Live Counter Store | Redis Cluster (16 shards, ~10 GB total RAM) | Live Token Buckets (rl:{caller}:rule_id → tokens, timestamp). | < 1ms (100M active keys) | Single-threaded atomic Lua scripts update counters in RAM with zero lock contention and auto-delete idle keys via TTL. |
| 3. Rule Store (Control Plane) | PostgreSQL or DynamoDB | rate_limit_rules and rule_audit_log (1,000–50,000 rules, < 50 MB). | < 10 reads/sec, < 1 write/sec | Never called on live API requests! Gateways cache rules in RAM and receive live updates in < 1s via Redis Pub/Sub. |
1. Why Redis for Live Counters? (Why Database Choice Matters Here)
On the live request path, we need to read, refill, and subtract counters up to 1,000,000 times per second in under 1ms.
- Why NOT a Relational DB (PostgreSQL / MySQL)? Disk-based SQL databases use row-level locks (
UPDATE ... WHERE) and a Write-Ahead Log (WAL). Every time a counter changes, Postgres must lock that user's row and flush the update to its on-disk WAL for crash recovery before committing. Doing disk WAL writes and row locks up to 1,000,000 times per second for throwaway counters that expire after a minute causes severe disk I/O bottlenecks, lock queues on busy keys, and 10–50ms latency spikes. - Why NOT a Disk/SSD NoSQL DB (DynamoDB / Cassandra)?
- Cassandra uses eventual consistency ("last-write-wins"), which overwrites and loses counter updates during concurrent bursts, and its distributed counters are too slow (5–15ms) for a gateway check.
- DynamoDB supports atomic updates, but disk-backed writes take 3–10ms p99 and paying per write at 1,000,000 writes/sec is prohibitively expensive for temporary counters that expire after a minute.
- Why NOT Memcached? Memcached is fast and in-memory, but it cannot run server-side Lua scripts. Because Token Bucket math requires reading two values (
tokensandtimestamp), calculating the refill, and writing both back, Memcached has to use optimistic locking (CAS/ Compare-And-Swap): a gateway reads the counter along with a version number (GETS), calculates the refill in gateway memory, and sends backCAS(key, new_value, version). If 100 requests for the same customer arrive at the same millisecond, 1 gateway wins theCASversion check and the other 99 fail with a version mismatch, forcing them to retry in a loop ("CAS retry storm"). - Why Redis (or Valkey) Wins: It keeps all counters 100% in RAM (< 0.5ms) and runs our Token Bucket math inside a single-threaded atomic Lua script that reads the bucket, updates the count, and sets an auto-delete timer (TTL) in one uninterruptible step with zero lock contention and zero retries.
2. PostgreSQL vs. DynamoDB for Rate-Limit Rules (Scale & Tradeoffs)
First, look at the scale of the Rule Store compared to the Live Counter Store:
- Data Size: Even with hundreds of API endpoints, 4 customer plans, and custom enterprise overrides, you only have 1,000 to 50,000 rules total (< 50 MB of data).
- Write Traffic: Engineers only create or edit rules in the Admin UI 10 to 100 times per day (< 1 write/sec).
- Read Traffic: Gateways never query this database on the 1,000,000 QPS live request path. The 50 gateways only read the rules on startup (plus a once-a-minute background refresh) and receive live edits via Redis Pub/Sub. That is < 10 reads/sec.
- How Rules Reach All 50 Gateways (Poll vs. Push Hybrid): Interviewers often ask how gateways learn when an engineer changes a rule:
- Why not Poll-Only (e.g., querying the DB every 60s)? Polling is simple, but waiting up to 60 seconds for a new rule to take effect is too slow when an on-call engineer is trying to block an active bot attack right now.
- Why not ZooKeeper or etcd? Coordination services like ZooKeeper/etcd support instant push notifications, but running a separate ZooKeeper cluster just to broadcast rate-limit rules adds unnecessary operational overhead.
- Our Choice (Push via Redis Pub/Sub + 60s Background Poll): Since we already run Redis, we use Redis Pub/Sub to push rule changes to all 50 gateways in < 1 second, and keep a 60-second background database poll as a safety net in case a gateway briefly disconnects and misses a Pub/Sub message.
Because < 50 MB and < 10 queries/sec is tiny compared to what any modern database can handle (10,000+ QPS), either Relational (PostgreSQL) or NoSQL (DynamoDB) works great here depending on your company's stack:
- Why Pick PostgreSQL / MySQL (Our Default): A single small Postgres instance handles 10,000+ reads/sec with ease. We default to Postgres because when an engineer updates a limit in the Admin UI, ACID transactions let us update the rule in
rate_limit_rulesand record who changed it inrule_audit_login one safe step, and SQL makes it easy to filter and search rules in the Admin UI. - Why Pick DynamoDB (NoSQL Alternative): You can store rules in DynamoDB using
client_tieras the Partition Key androute_patternas the Sort Key. Because gateways load all active rules into memory anyway, you don't need complex SQLJOINs. DynamoDB is a great choice if your team wants zero database server maintenance and built-in multi-region replication (DynamoDB Global Tables) so a rule updated in the US automatically syncs to Europe.
3. How We Store Keys in Redis Cluster (And Enforce Multiple Time Windows)
- What Lives Inside Each Redis Counter Key (And Automatic Cleanup):
For each active user, Redis stores a tiny Hash with just two numbers: how many tokens they have left (
tokens) and the timestamp of their last request (last_updated). Every time we update a key, we also set an automatic expiration timer (TTL) equal to twice the time needed for that bucket to refill to 100%. Once an idle user's bucket is completely full again, keeping it in Redis is identical to deleting it (because a missing key always starts 100% full). Auto-deleting full buckets ensures Redis memory never fills up with one-time visitors. - Enforcing Two Time Windows at Once (Short Burst + Daily Quota):
Interviewers often ask: "What stops a customer with a 1,000,000 requests/day limit from sending all 1,000,000 requests in 10 seconds and crashing your servers?"
To prevent this, we give the customer two separate buckets in Redis:
- A short-term burst bucket (
rl:{user_123}:second, e.g., 500 requests per second) - A long-term daily bucket (
rl:{user_123}:day, e.g., 1,000,000 requests per day) Every incoming request must take 1 token from both buckets to be allowed through.
- A short-term burst bucket (
- Keeping Both Counters on the Same Redis Server (Redis Cluster Hash Tags):
A Redis Cluster divides data across multiple servers by hashing each key name across 16,384 hash slots (with each of our 16 Redis shards owning 1,024 slots). Normally, Redis hashes the entire key string to pick the server, so
rl:user_123:secondmight land on Shard 2 whilerl:user_123:daylands on Shard 11. Because a single Redis script cannot update two different servers at once, we wrap the user ID in curly braces{user_123}(called a Redis hash tag). The curly braces tell Redis Cluster: "Only hash the text inside{...}when picking the server." That guarantees both the per-second counter and the daily counter foruser_123always live on the exact same Redis server, so our gateway can check and update both limits in a single network call.
4. Example Rule Schema (If Using PostgreSQL)
CREATE TABLE rate_limit_rules (
    rule_id             VARCHAR(64) PRIMARY KEY,      -- e.g., 'enterprise_post_charges'
    client_tier         VARCHAR(32) NOT NULL,         -- 'free', 'pro', 'enterprise', 'anon'
    route_pattern       VARCHAR(128) NOT NULL,        -- 'POST:/v1/charges'
    bucket_capacity     INT NOT NULL,                 -- Max burst (e.g., 1000)
    refill_rate_per_sec NUMERIC(10, 4) NOT NULL,      -- Steady rate (e.g., 100.0)
    failure_mode        VARCHAR(16) DEFAULT 'OPEN',   -- 'OPEN' (abuse) or 'CLOSED' (billing)
    rollout_stage       VARCHAR(16) DEFAULT 'SHADOW', -- 'SHADOW', 'SOFT_WARN', 'CANARY', 'ACTIVE'
    updated_at          TIMESTAMPTZ NOT NULL DEFAULT NOW()
);
9Staff Deep Dives & Production Curveballs
Scenario-based analysis for Staff-level depth
Once your core design is on the whiteboard, the interviewer will spend the next 20 minutes testing how your system survives real-world failures, edge cases, and human mistakes.
Deep Dive 1: What Happens When Redis Slows Down or Crashes? (Master-Replica Failover, 5ms Circuit Breaker & "Silent Fail-Open")
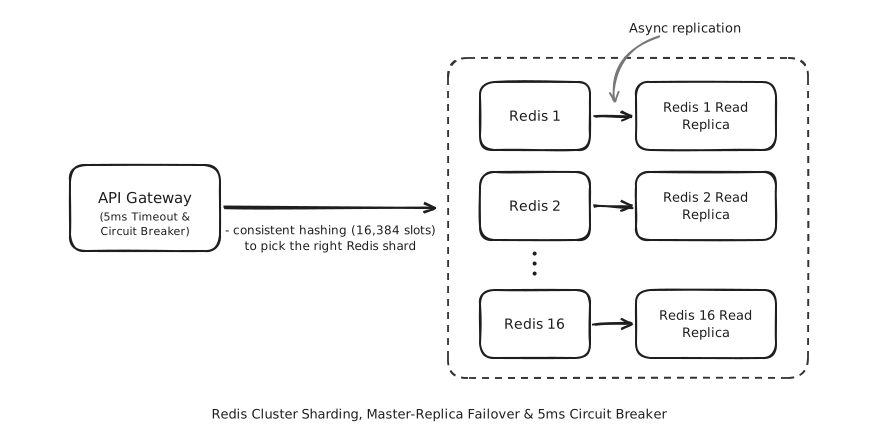
For high availability, each of our 16 Redis primary shards has an asynchronous Read Replica ready for automatic Master-Replica failover. However, if a candidate stops at "We have Redis replicas, so a replica will take over," they miss what actually happens during the 10 to 15 seconds it takes Redis Cluster to detect a dead primary and promote its replica (or when a primary doesn't crash completely, but stalls at 80ms due to a noisy cloud neighbor). If your 50 gateways wait 80ms on every request at 1,000,000 requests/sec, your gateways will run out of worker threads long before the replica finishes taking over:
- t = 0s: Redis primary stalls or crashes; response time jumps from 1ms to 80ms+.
- t = 0–5s: Gateway worker threads pile up waiting for Redis while replica promotion is still running.
- t = 10s: All gateway worker threads are stuck waiting; new user requests sit in a full queue.
- t = 15s: API Gateways start returning
HTTP 503/504errors to 100% of customers. Your rate limiter just caused a total site-wide outage!
The 4-Step Staff Solution (Surviving Both Slow Shards and the 15s Replica Failover Window):
- Master-Replica Failover + Strict 5ms Timeout: Run a standby replica for every Redis primary shard so hardware crashes recover automatically, and set a hard 5ms timeout on all gateway Redis calls so slow calls abort immediately instead of blocking gateway threads.
- Trip a Circuit Breaker: If more than 5% of calls to a Redis shard time out (or 3 calls fail in a row), the gateway trips a Circuit Breaker (
OPEN) for 15 seconds and stops calling that shard while it recovers or promotes its replica. - Switch to a Local In-Memory Limit (Don't Just Let Unlimited Traffic In):
While the circuit breaker is open, each of the 50 gateways switches to counting in its own local RAM using a safe fallback limit (e.g.,
2 × (Global Limit / 50 gateways)). Even if a Redis shard is completely unreachable, bots are still blocked near their normal limit, and zero gateway threads get stuck. - Alert on "Silent Fail-Open" (
rate_limit_bypassedMetric): The sneakiest bug in rate limiting is when Redis breaks, your gateways quietly fall back to local mode, and nobody notices for 3 days because customers aren't complaining when their requests succeed!- Every time a request skips Redis and uses the local fallback, increment a metric:
rate_limit_bypassed. - On-Call Alert: If
rate_limit_bypassedexceeds 1% of traffic for more than 5 minutes, PagerDuty wakes up the on-call engineer immediately. - 3 AM Runbook: (1) Check which Redis shard is unhealthy and replace/failover; (2) verify local fallback limits are active; (3) if backend database CPU is climbing while degraded, lower the local fallback limit from 2x to 1x with a config push.
- Every time a request skips Redis and uses the local fallback, increment a metric:
Deep Dive 2: Clock Skew Across 50 Gateway Servers
- The Bug: Suppose Gateway 1's clock is 200ms fast. Gateway 1 processes a request for User A and saves
last_updated = 1200in Redis. One millisecond later, User A's next request lands on Gateway 2, whose clock saysnow = 1001. When Gateway 2 calculatesnow - last_updated(1001 − 1200), it gets −199ms (negative time!), which subtracts tokens or breaks the counter. - The Two-Part Staff Fix:
- Never Allow Negative Time: In the Redis script, always clamp elapsed time so it can never be below zero:
math.max(0, now - last_ts). - Use Redis's Own Clock (
redis.call('TIME')): Never pass timestamps from the 50 gateway servers! Instead, have the script ask Redis for its current time usingredis.call('TIME'). Because a specific user's counter (rl:user_A) always lives on one specific Redis server, only that single Redis server's clock is ever used for User A's math, wiping out cross-server clock drift completely.
- Never Allow Negative Time: In the Redis script, always clamp elapsed time so it can never be below zero:
Deep Dive 3: Shared Office IPs (NAT), Fake API Keys & 100,000-IP Botnets
1. Shared Office or Hospital IP Addresses (Corporate NAT)
If you put a blanket limit of 60 requests/min per IP address on your API, 5,000 employees sharing one corporate Wi-Fi IP (or thousands of mobile users sharing one cell-tower IP) will get blocked within 2 seconds.
- The Staff Fix:
- Never rate-limit logged-in traffic by IP address. Always check
user_idorapi_keyfirst, so each employee at the hospital gets their own personal limit. - For logged-out pages (
/login,/search): Only fall back to IP address when the user isn't logged in. Use a generous limit per IP, and if a shared IP spikes on a logged-out page, show a CAPTCHA challenge instead of hard-blocking the whole building.
- Never rate-limit logged-in traffic by IP address. Always check
2. Attacker Sending Millions of Random Fake API Keys (Memory Exhaustion Attack)
Suppose an attacker sends 5,000,000 requests/min with made-up headers (X-API-Key: fake_1, fake_2, fake_3...). If your rate limiter creates a brand-new counter in Redis (or gateway memory) for every fake key, Redis will run out of memory (OOM) and crash!
- The Staff Fix (Check Key Validity Before the Rate Limiter):
Fake keys should never get a rate-limit counter. Before calling the rate limiter, the API Gateway checks if the API key is valid using two fast local checks:
- Cryptographic Signature / Checksum: Format API keys with a built-in HMAC signature or checksum (like Stripe's
sk_live_...keys) so the gateway can verify the key's math in CPU in 0.001ms. - In-Memory Bloom Filter: Each gateway keeps a Bloom filter of all active API keys in local RAM. A Bloom filter is a compact bit-array that can represent 10,000,000 valid keys in just ~12 MB of memory. When a request arrives, the gateway hashes the key against the local Bloom filter: if any bit is 0, the key is guaranteed to be fake and is rejected immediately with
HTTP 401 Unauthorizedin 0.01ms with zero memory created in Redis.
- Cryptographic Signature / Checksum: Format API keys with a built-in HMAC signature or checksum (like Stripe's
3. Botnet Rotating Across 100,000 IP Addresses (2 req/min per IP)
If an attacker uses 100,000 infected home routers to try stolen passwords on /login, sending just 2 requests/min from each IP, a per-IP rate limit of 60/min will never trigger.
- The Staff Fix:
- Rate-Limit by the Target Account Being Attacked: On
/login, keep a counter per target email/username (e.g., after 5 failed password attempts foralice@gmail.comfrom any IP address, require a CAPTCHA or lock login for 15 minutes). - Group by TLS/HTTP Header Patterns & Global Failure Rate: Even when an attacker rotates across 100,000 residential IP addresses, bots running the same attack script share identical TLS/HTTP header patterns (the exact same TLS cipher suites, extensions, and HTTP header ordering on every request). The edge or API Gateway hashes these TLS/HTTP header patterns into a single client fingerprint (such as a JA3/JA4 fingerprint) and rate-limits that fingerprint across all 100,000 IPs at once, while also turning on CAPTCHA challenges on
/loginif global401 Login Failederrors spike across the site.
- Rate-Limit by the Target Account Being Attacked: On
Deep Dive 4: Hot Keys ("One Customer Is 90% of Our Traffic")
- Why 16 Redis Servers Don't Help Automatically:
Having 16 Redis servers spreads out millions of different keys. It does nothing for one single key (
rl:hot_customer), because that one key name always hashes to Redis Server #1. - What Breaks First (Collateral Damage to Innocent Customers): Redis Server #1's single CPU core hits 100% at ~80,000–100,000 ops/sec. Every other innocent customer whose counter happens to live on Redis Server #1 suddenly experiences timeouts, while Redis Servers #2 through #16 sit idle at 5% CPU!
Three Staff Fixes (In Order of How Fast They Stop the Bleeding):
- For Abusive Keys Over Their Limit (Cache the
429 BlockedStatus in Gateway Memory for 10 Seconds): Once Redis tells a gateway thatrl:abuser_keyis out of tokens (429), the gateway remembersrl:abuser_key = BLOCKEDin its own local RAM for the next 10 seconds. For those 10 seconds, all 50 gateways reject the attacker's 80,000 requests/sec in 0.01ms without sending a single network call to Redis. Redis load drops to zero immediately. - For Legitimate High-Volume Partners (Batch Token Leasing from Section 7): Checking out batches of 500 tokens at a time already reduces 80,000 req/sec down to just 160 Redis calls/sec.
- If One Key Still Needs Massive Redis Throughput (Split into 16 Sub-Keys
rl:key:1..rl:key:16): Append a random number1..16to the key name and give each sub-key 1/16th of the customer's total limit. Now the 80,000 req/sec load spreads evenly across all 16 Redis servers (5,000 req/sec per server).
Deep Dive 5: Multi-Region Rate Limiting & GDPR Privacy
- Why a Single Global Redis Fails: The speed of light across the Atlantic Ocean takes ~75ms round-trip. Having European gateways call a US Redis server on every request makes every European API call 75ms slower.
- The Staff Multi-Region Solution:
- Put an Independent Redis Cluster in Each Region: European users hit the Frankfurt gateway + Frankfurt Redis (< 1ms); US users hit the Virginia gateway + Virginia Redis (< 1ms).
- For Bot & Abuse Limits (Keep Regions Separate): Let each region enforce abuse limits independently. If an attacker hits both the US and Europe at the exact same second, they might briefly get 2x the burst limit globally, which is a tiny tradeoff compared to saving 75ms on every customer request.
- For Enterprise Global Quotas (Split the Quota by Region): If a global customer pays for 10,000 req/min and normally sends 70% of their traffic in the US and 30% in Europe, give the US Redis cluster 7,000 req/min and the Europe Redis cluster 3,000 req/min. If Europe gets busy, a background job shifts unused quota between regions every 15 seconds, never on the live request path.
- The GDPR Privacy Bonus: Rate-limit keys often contain
user_idor client IP addresses, which count as personal data (PII) under European GDPR laws. Sending European users' IP counters to a US Redis cluster can create legal compliance headaches. Keeping European counters strictly inside Frankfurt Redis (and only syncing company-level totals across regions) keeps you GDPR-compliant by design!
Deep Dive 6: Multi-Tenant Fairness, Dropping Background Work First & Stopping Retry Storms
1. Guaranteed Minimums + Shared Extra Capacity (Stopping Noisy Neighbors)
Giving a big customer a 5,000 req/sec limit doesn't help if your backend database is having a slow day and can only handle 4,000 req/sec total. That one customer will eat 100% of your database capacity and lock out smaller customers.
- The Staff Fix: Give every customer two numbers:
- A Guaranteed Minimum (e.g., 500 req/sec): Always allowed, even when servers are busy.
- A Shared Burst Limit (up to 2,000 req/sec): Only allowed when overall backend database CPU is healthy (< 70%). When the database gets busy, heavy customers are automatically throttled back to their guaranteed minimum so smaller customers aren't starved.
2. Drop Low-Priority Background Traffic First (Priority Load Shedding)
Not all API calls are equally important. Tag every API endpoint with a priority level at the gateway:
- Priority 0 (Revenue-Critical):
POST /v1/checkout,POST /v1/payments - Priority 1 (Live User UI):
GET /v1/orders,GET /v1/profile - Priority 2 (Background / Can Wait): Webhook status checks, analytics events, bulk CSV exports
When backend database CPU crosses 85%, the API Gateway automatically tightens rate limits on Priority 2 background endpoints (returning HTTP 429 with Retry-After: 30), freeing up server capacity so Priority 0 live checkouts keep succeeding at 100%.
3. Stopping Client Retry Storms (Retry-After + Random Jitter)
If you return HTTP 429 with Retry-After: 10 to 10,000 throttled clients, poorly written clients will all wait 10 seconds and slam your server at the exact same millisecond 10 seconds later.
- For Official SDKs / Trusted Clients: Add a random delay ("jitter") to the
Retry-Aftertime (e.g., retry anywhere between 10 and 18 seconds) so retries spread out smoothly. - For Badly Behaved / External Clients: Assume they will ignore
Retry-Afterand retry in a tightwhile(true)loop. Use the 10-second Local "Blocked" Cache in gateway memory (Deep Dive 4) to drop their repeated retries in 0.01ms before they touch Redis or your backend.
Deep Dive 7: Rolling Out New Rules Safely & Handling a Black Friday Flash Sale
1. The 4-Step Safe Rollout Pipeline for New Rate Limits
Most outages are caused not by traffic spikes, but by an engineer pushing a bad configuration rule (for example, setting /api/v2/checkout to 10 req/min instead of 10,000 req/min). How do we prevent a bad rule from taking down production? Never turn a brand-new rate limit straight onto 100% hard blocking. Enforce a 4-Step Rollout:
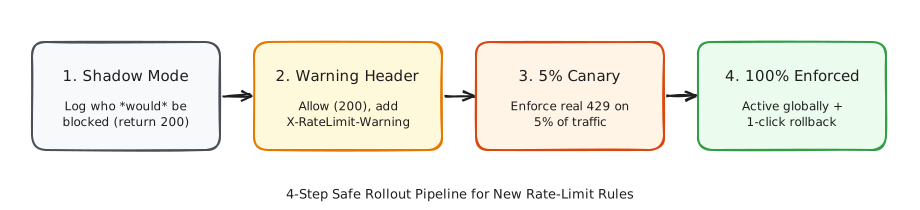
2. Crisis Scenario: Real Buyers Getting 429 Errors on Black Friday
Suppose traffic jumps 10x during a Black Friday sale, and on-call pages you because real shoppers are getting HTTP 429 on /checkout.
- The Common Trap: Checking the Redis dashboard, seeing that Redis is healthy and counting accurately, and concluding "The rate limiter is working as designed."
- The Staff Response:
- Check Backend Server Health First (CPU, Database Latency, 5xx Errors): Remember why the rate limiter exists: its job is to protect the backend servers, not to enforce arbitrary numbers! If your backend servers are sitting at a healthy 40% CPU while real buyers are getting blocked with
HTTP 429, your rate limit is set too low and is costing the company money. - Flip a Temporary 2-Hour Override: Use the Rule Management UI to temporarily raise checkout rate limits by 2x–3x with an automatic 2-hour expiration timer (pushed to all gateways in < 1 second via Pub/Sub), while watching backend CPU closely.
- Long-Term Fix: Configure Dynamic Burst Limits that automatically allow higher per-user limits whenever overall backend server CPU is healthy (< 70%).
- Check Backend Server Health First (CPU, Database Latency, 5xx Errors): Remember why the rate limiter exists: its job is to protect the backend servers, not to enforce arbitrary numbers! If your backend servers are sitting at a healthy 40% CPU while real buyers are getting blocked with
10In the Wild: How Stripe, Figma & Cloudflare Do It
Sharing how real companies solve this shows the interviewer your design is grounded in production reality:
1. Stripe: Two Separate Systems (Fast Abuse Limiter vs. Strict Billing Limiter)
Stripe separates API protection from paid usage billing. At the front door, Stripe's API gateways run a fast Token Bucket limiter that protects backend servers from runaway scripts and concurrency spikes (Fail-Open), returning RateLimit-Limit, RateLimit-Remaining, and RateLimit-Reset headers. Paid billing counters run on a separate, strictly accurate pipeline (Fail-Closed) so a traffic spike on the abuse limiter never corrupts financial data, and a billing database maintenance window never blocks live payment API calls.
2. Figma: Slowing Down Updates Instead of Returning Hard 429 Errors
In a live multiplayer app over WebSockets (where 50 people are moving cursors on the same design canvas), returning a hard HTTP 429 error and dropping messages breaks the shared screen for everyone. Instead of hard rejections, Figma uses graceful slowdown (backpressure): when a file gets too busy, the server automatically lowers how often cursor positions update (batching updates every 100–200ms instead of 16ms) rather than disconnecting users.
- Key Takeaway: For standard HTTP APIs, reject fast with
HTTP 429. For live WebSocket or streaming apps, slow down update frequency instead of dropping the connection.
3. Cloudflare: Filtering Traffic in Layers at the Edge
Cloudflare doesn't use a single rate limiter for everything; it filters traffic in three layers from cheapest to most specific:
- Layer 1 (Network Edge): Drops raw network packet floods immediately before they reach web servers.
- Layer 2 (Bot & Challenge Layer): Unauthenticated requests that look like automated scripts get a quick browser check / CAPTCHA before touching backend APIs.
- Layer 3 (Per-User API Gateway): Clean, logged-in traffic is checked against per-user and per-API-key Token Buckets.
11Staff Insider: 5 Contrarian Truths Worth Sharing in an Interview
Most candidates repeat textbook definitions. Sharing battle-tested, slightly contrarian lessons from real production incidents immediately tells a Staff+ interviewer you have operated high-scale infrastructure in the real world:
- "100% Exact Global Rate Limiting" Is a Trap That Will Take Down Your API: Candidates often burn 15 minutes trying to make distributed counters 100% exact across every server and region. In production, chasing 100% global accuracy forces synchronous network locks on every request, which turns your rate limiter into a latency tax and an outage amplifier. For abuse protection, accepting 2–5% drift via local batch leasing cuts 98% of Redis network calls and keeps latency under 1ms. Save strict 100% accuracy for your asynchronous billing pipeline.
- Returning
HTTP 429Without Jitter Doesn't Stop a Spike (It Synchronizes a DDoS Against Yourself): Textbooks say "just return HTTP 429 andRetry-After: 5." In production, if 50,000 mobile clients or partner SDKs get rejected during a spike and all seeRetry-After: 5, they will all sleep until second 5.000 and fire again at the exact same millisecond. That creates a synchronized retry storm worse than the original spike. Always add randomized jitter toRetry-Aftervalues (e.g., returning between 4 and 8 seconds) and enforce retry backoff budgets in your client SDKs. - Bad Rate-Limit Configs Cause More Outages Than Actual DDoS Attacks: Engineers obsess over Redis failover and Lua scripts, yet at companies like Cloudflare, Stripe, and GitHub, the #1 cause of rate-limiter outages isn't Redis crashing. It is an engineer deploying a typo in a rule (like 10 req/min instead of 10,000 req/min) that blocks paying customers. A rate limiter without Shadow Mode (dry-run logging) and a 1-click global kill switch is a loaded gun pointed at your own revenue.
- Counting "Requests per Second" Alone Won't Save Your Database:
Treating every HTTP request as 1 token is a classic trap.
GET /healthtakes 0.1ms of CPU, whilePOST /export-reportor a 100K-token AI prompt takes seconds of database or GPU compute. A caller well under their "100 req/min" limit can still melt your database if all 100 calls hit your most expensive query. Mature production systems evolve from request-count limiting to cost-based limiting, where heavy endpoints deduct 10–50 tokens per call based on actual compute cost. - Below 20,000 QPS, Building This From Scratch Is Resume-Driven Development: In a 45-minute interview, you are obviously expected to design the custom distributed limiter. Still, dropping a 15-second pragmatic reality check is pure Staff-level signal: "In real life, below 20K QPS I wouldn't let my team spend 3 months building and maintaining a custom two-tier Redis token-leasing cluster. We would turn on Cloudflare, Envoy, or AWS API Gateway rate limiting on day one, and only build this custom architecture when hot-key scale, multi-tenant fairness, or custom token-cost rules force our hand."
12What Is Expected at Each Interview Level?
Mid-Level
A mid-level candidate will focus mostly on breadth (80% breadth vs. 20% depth) and should craft a working high-level design that meets the functional requirements, even if some components remain high-level abstractions. Your interviewer will spend time confirming you understand what each component does: if you put Redis on the board, expect them to ask how it stores counters and why local gateway memory alone fails behind a load balancer. You should drive the early stages like requirements gathering, define the HTTP 429 response headers, clearly explain one rate-limiting algorithm (Token Bucket works well), place the rate limiter sensibly in the architecture (inside the API Gateway), and when asked about scaling, recognize the need to shard Redis with a rough understanding of how that works.
Senior
As a senior candidate, expectations shift toward more technical depth (60% breadth, 40% depth), where you should confidently discuss trade-offs between different rate-limiting algorithms and justify your choices. You should move quickly through basic algorithm selection to spend time on distributed systems challenges: spotting race conditions when multiple gateways read and update Redis concurrently, knowing that Redis counter updates must be atomic, and explaining why server-side Lua scripts outperform optimistic locking under heavy contention. You are expected to clearly explain the trade-offs between fail-open and fail-closed strategies, justify why Redis fits live counters while relational or NoSQL databases fit rule storage, proactively identify issues like hot keys, clock skew across servers, and shared corporate IP addresses, and have a clear plan for pushing configuration changes to gateways.
Staff+
Staff+ candidates are evaluated on deep production judgment (40% breadth, 60% depth) and exceptional proactivity, drawing from real-world experience operating distributed systems at scale. You shouldn't wait for the interviewer to point out flaws; you should surface failure modes, edge cases, and operational risks yourself. Early on, you reframe the problem by separating fast abuse protection (which must fail-open) from strict billing enforcement (which must fail-closed) and multi-tenant fairness. You proactively identify how a single heavy customer can overload an individual Redis shard and solve it with local token leasing in gateway memory while explicitly naming the accuracy trade-off. Rather than stopping at "we'll fail-open if Redis goes down," you pair your circuit breaker with alerting on bypassed checks so silent failures never go unnoticed, address multi-region latency and data privacy boundaries across geographies, and handle safe rule rollouts (shadow mode and canary deployments) and priority load shedding as routine parts of production operations.
A Senior engineer builds a rate limiter that counts accurately when all servers are healthy. A Staff engineer builds a rate limiter that protects the business even when traffic spikes 10x, one giant customer goes rogue, a team deploys a bad config, and the rate limiter's own Redis cluster is on fire.